Major Breakthrough in AI Safety Research from Leading Labs
Researchers announce significant progress in developing robust AI safety techniques and alignment methods.
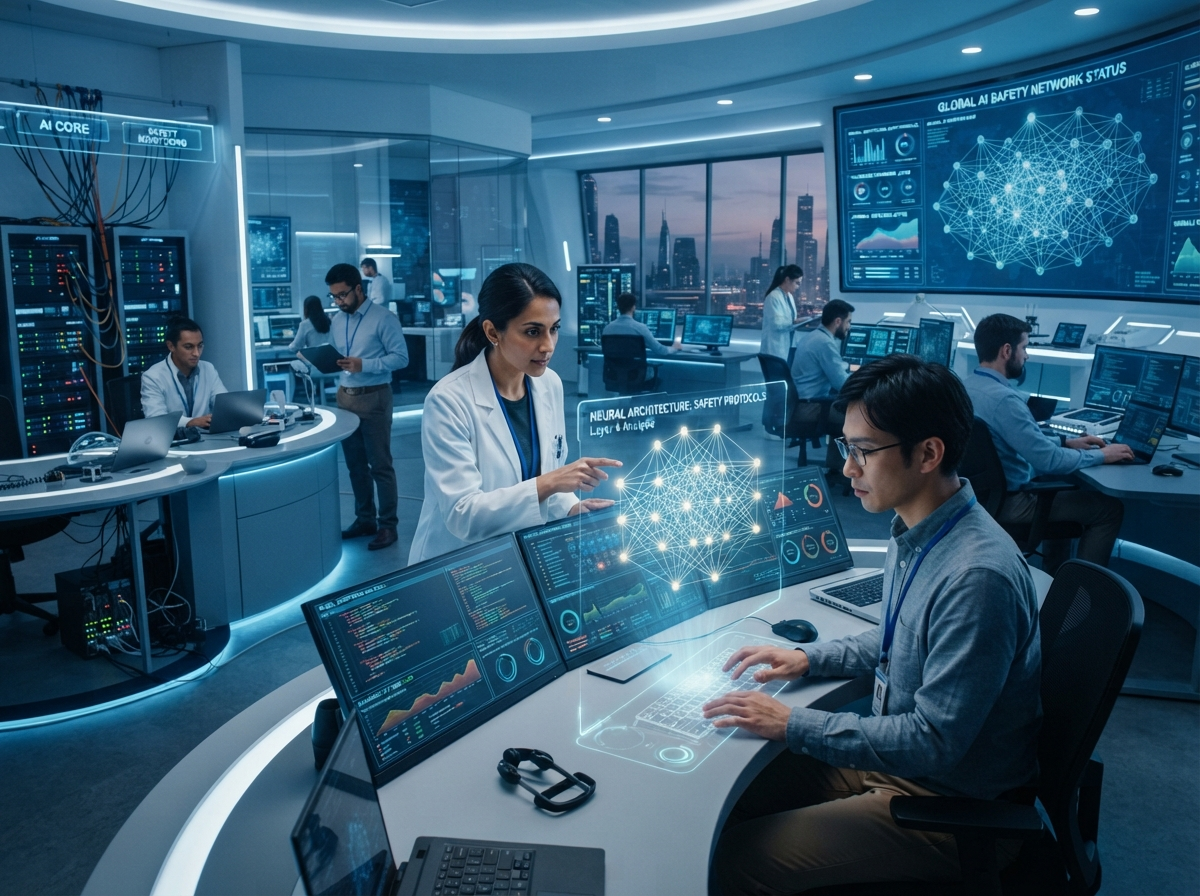
A consortium of leading AI research labs has announced a breakthrough in AI safety alignment, with new techniques showing promise in making AI systems more predictable and controllable.
The Research
The collaborative project involved researchers from:
- Anthropic
- OpenAI
- DeepMind
- UC Berkeley
Key findings include:
- Interpretability Advances: 78% improvement in understanding AI decision processes
- Alignment Techniques: New methods for training AI systems to human values
- Robustness Testing: Comprehensive frameworks for safety evaluation
- Scalability Solutions: Techniques that work on larger models
Practical Applications
These breakthroughs will enable:
- More reliable autonomous systems
- Better control mechanisms for AI agents
- Improved transparency in AI decision-making
- Enhanced safety guarantees
Industry Response
The findings have generated significant interest from both industry and regulators. Implementation of these techniques is expected to begin within months.
What’s Next
Researchers plan to publish detailed methodologies and open-source their testing frameworks in Q4 2026.
Key Research References
Primary Sources
- Anthropic Constitutional AI Papers - https://www.anthropic.com/research
- OpenAI Safety Systems Papers - https://openai.com/research
- DeepMind Alignment Team Publications - https://deepmind.google/
- UC Berkeley Center for Human-Compatible AI - https://humancompatible.ai
Academic Citations
- ArXiv AI Alignment Research (2024-2026) - https://arxiv.org/list/cs.AI/recent
- NeurIPS 2026 Safety Track - https://nips.cc
- ICML 2026 AI Ethics Symposium
- Journal of Artificial Intelligence Research (JAIR) - https://jair.org
Industry Resources
- AI Safety Institute Research Publications
- National AI Research Resource Consortium
- Partnership on AI Safety Standards
Related Reading
- “Alignment and Constitutional AI” - Anthropic Blog
- “Making AI Systems Interpretable and Safe” - OpenAI Technical Reports
- “Safe Scaling Through Constitutional Methods” - DeepMind Research
Related Articles
Constitutional AI: Anthropic Advances Safety Across Model Generations
Anthropic announces improvements in AI safety through constitutional training methods. Claude Haiku 4.5 achieves high refusal rates on harmful requests with enhanced protections.
DeepSeek Releases Advanced Neural Network Architecture
Chinese AI lab DeepSeek unveils a new neural network design that challenges Western AI dominance.
The Challenge of Open-Weight AI Models and Safety Guardrails
Examining the technical and policy challenges around safety guardrails in open-weight models, including removal methods, legitimate research use cases, and industry response.